03. Large Language Models (LLMs), GPTs, and the Architecture
Published 2026-09-14
Core Theme: A large language model is not an encyclopedia in which truth is stored. It is a powerful probabilistic engine that has captured the patterns of human language in mathematical vectors and matrices — and predicts the most plausible next word.
This chapter is the public-officer edition of CM-02: Large Language Models (LLMs), Neural Networks & Cognitive Biomimicry. The general explanation is there; this page keeps what changes when the work is a public office.
AI, generative AI, LLM, GPT — what is the difference?
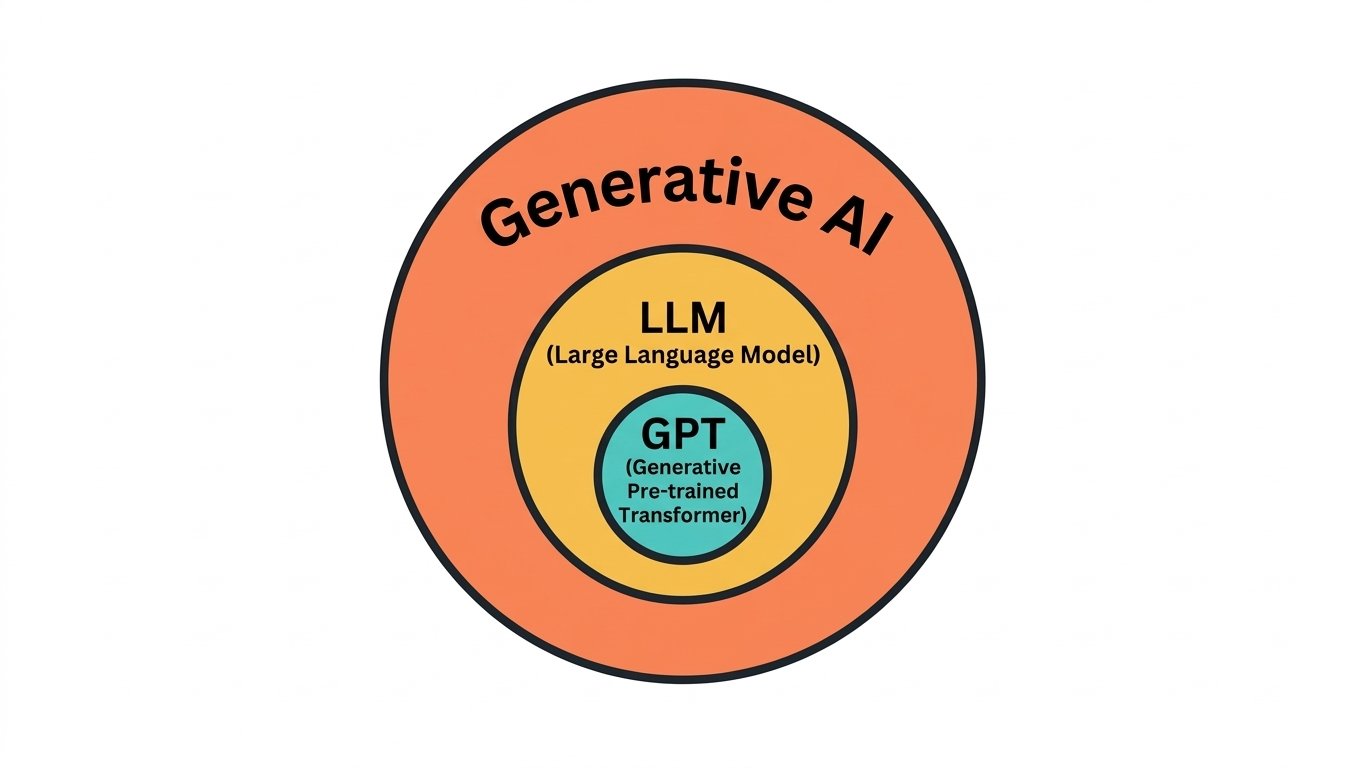 Figure 3.1: The conceptual hierarchy from AI to GPT — Artificial Intelligence (AI) → Generative AI → Large Language Models (LLMs) → Generative Pre-trained Transformers (GPT).
Generative AI is a subset of artificial intelligence. Its defining property is that it produces new content — text, images, code, sound — rather than classifying or scoring content that already exists. The distinction between analysing and generating is the one that matters most in practice, and Chapter 02 sets it out in full.
Large language models are one kind of generative AI, specialised in language. Such a model has consumed effectively all the digitised writing available to it and extracted, mathematically, the patterns by which human language holds together. It is worth being precise about what was extracted: not the facts in those documents, but the statistical shape of how words follow one another. That distinction returns later in this chapter, and it explains almost everything people find puzzling about these systems.
The practical point is that this is one family, not several competing inventions. OpenAI's ChatGPT, Google Gemini, Anthropic Claude and DeepSeek all run on the same Transformer principle. They differ in scale, in training data and in the values instilled during fine-tuning — which, as the section on Sinhala below shows, has substantial consequences for an officer working in this country. The full technical evolution is charted in Idasara Academy's published article The Gen AI Evolutionary Journey: 2017 to 2035.
From Mechanical Biomimicry to Cognitive Biomimicry: Neural Networks
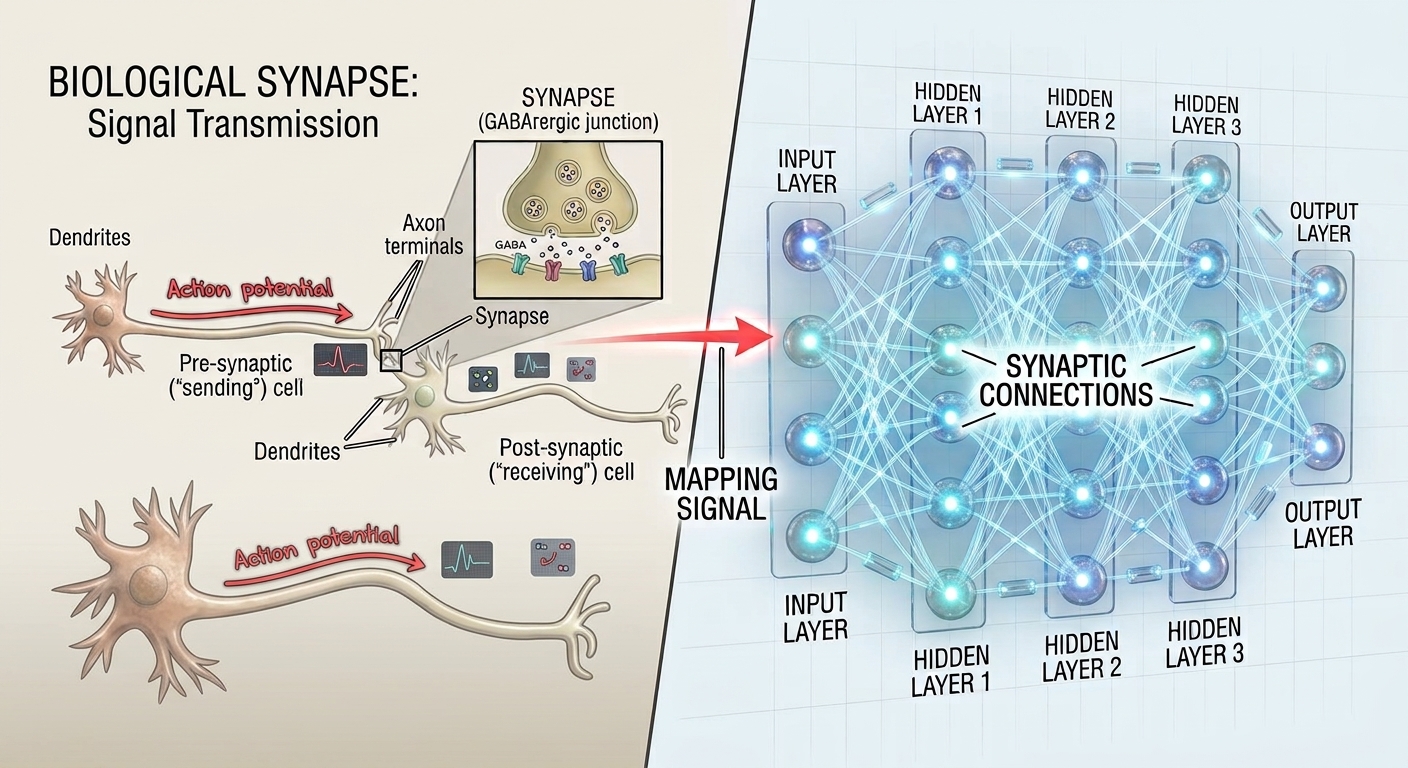 Figure 3.3: Cognitive biomimicry — a direct comparison of the brain's biological synapse and electrical signaling (action potential) with the mathematical construction of an artificial neural network: input layer, hidden layers 1–3, output layer, and synaptic weightings.
The 1:1 Engineering Parallel Between the Biological Brain and the Artificial Neural Network (LLM):
| # | Biological Brain | Artificial Neural Network / LLM | Engineering Function |
|---|---|---|---|
| 01 | Biological Neuron | Artificial Node / Layer | Aggregates signal inputs and transmits them to the next nodes through an activation function. |
| 02 | Synapse (the connection) | Weight / Parameter | The numerical value that determines the strength of information flow between two nodes (modern LLMs carry hundreds of billions of these). |
| 03 | Synaptic Plasticity | Backpropagation & Gradient Descent | When the model errs, the network's weights are mathematically updated to minimize that error — this is how it learns. |
| 04 | Childhood Experience & Learning | Pre-training on Trillions of Tokens | By reading trillions of words and patterns, the network deposits the probabilistic patterns of language and the world within itself. |
| 05 | Cognition & Response | Inference / Next-Token Generation | When a new prompt arrives, the trained network computes and instantly generates the most fitting sequence of next words. |
Evolutionary Optimization and the Critical Boundary Line
Where the analogy stops. Any leader of public administration needs this boundary drawn sharply:
Shaping the bullet train's nose like a kingfisher's beak does not turn that iron train into a living kingfisher that flaps its wings, flies, and lays eggs. It remains a mechanical train running on rails.
The reason this matters is not philosophical fastidiousness. It is that a system which sounds like a person invites you to treat it like one, and for an officer that leads directly to two errors: believing what it says because it sounds confident, and treating it as answerable for a decision that remains entirely yours. Anthropomorphism is not a harmless indulgence. Getting this boundary right is what lets you take the enormous efficiency on offer without inheriting the delusion that comes attached to it.
What is inside the Transformer brain?
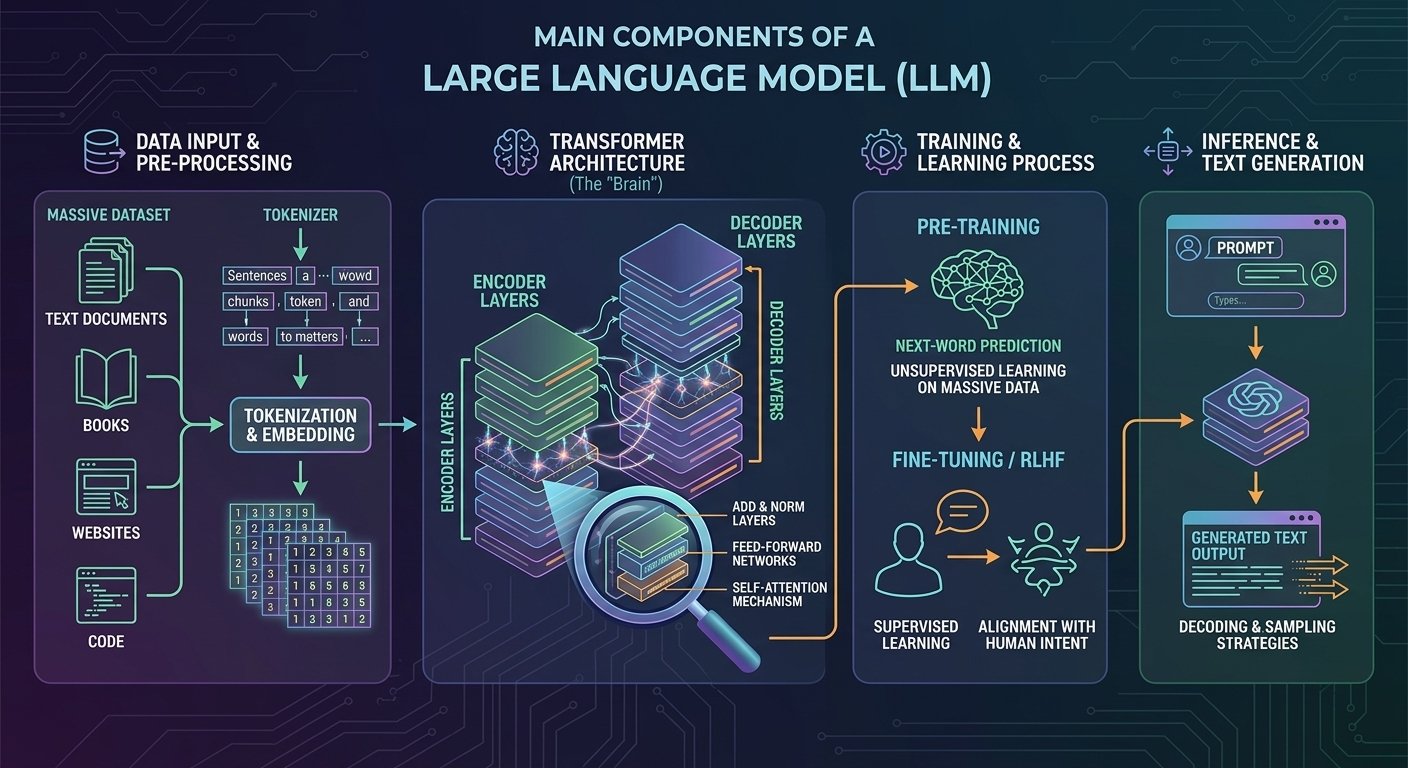 Figure 3.4: The fundamental architecture of a large language model (LLM) — the massive dataset, tokenization and embedding, the Transformer brain, the training process (pre-training & RLHF), and inference output.
Stage two: tokenization and embedding
Vector embedding then gives every token coordinates in a mathematical space of thousands of dimensions, positioned so that words close in meaning sit close together. "Divisional Secretary" and "District Secretary" end up as near neighbours. That single property is what allows a model to handle a question it has never seen: it does not need the exact phrase, only something nearby in the space. It is also why a model can confuse two things that are similar in usage but critically different in law — proximity in meaning-space is not identity.
Stage four: training and learning
Fine-tuning with human feedback, known as RLHF, comes after. Human experts rank the model's answers and the model is adjusted toward responses that are appropriate, safe, courteous and truthful — aligned with human intent, including the standards expected in public service. Pre-training produces capability; RLHF produces a system that behaves like an assistant rather than an autocomplete. It is also, being human, the stage where cultural assumptions enter most directly.
How does a model learn?
There is no instruction anywhere in this process, and no comprehension. The model is not told what a verb is, that Colombo is in Sri Lanka, or that a pension has eligibility rules. All of it arrives as a by-product of getting better at predicting the next word — which is genuinely remarkable, and also the reason the knowledge is uneven in ways that are impossible to predict from the outside.
Why is an LLM a plausibility engine, not a truth engine?
For a public officer, this is the single engineering fact to engrave permanently in mind. Everything else in this chapter is background; this is the part that changes how you work.
Follow that mechanism to its conclusion and the most dangerous property of these systems becomes obvious rather than surprising. Fluency and accuracy are produced by the same process, so they arrive together and cannot be separated by inspection. A correct answer and a fabricated one are generated identically, expressed with identical confidence, and formatted in identically beautiful official prose. There is no tremor in the voice on the invented circular number. The hallucination is not a malfunction in which the machine has failed to work properly; it is the machine working exactly as designed, on a question where the plausible answer and the true answer happened to diverge.
This reverses the ordinary human heuristic, and that is precisely why experienced officers are caught by it. We are trained from childhood to read fluency and confidence as evidence of competence, because in humans it usually is — a person who speaks precisely about pension regulations has generally studied them. That inference is sound for people and worthless for models. An officer must never be seduced by the model's form, and must always verify its truth. Chapter 08 sets out how to do that verification systematically.
Why do models differ in Sinhala and Tamil?
A complaint surfaces in every session with officers, and it is entirely fair: ask ChatGPT something in Sinhala and the answer is sometimes nonsense; ask the same thing in English and it is superb. Why?
Western knowledge bias
American models such as ChatGPT and Claude are trained overwhelmingly on the Western world's English literature, Western law and Western data. What they hold about Eastern cultures, Sri Lankan administrative circulars, or the texture of our rural life is a sliver by comparison.
This produces two distinct failures, and the second is the dangerous one for an officer. The model may write awkward Sinhala, which is obvious and therefore harmless. Or it may write fluent, confident English about a Sri Lankan circular or administrative rule it has almost no data on — and that failure is invisible, because the prose quality gives no signal about the knowledge behind it.
Why Tamil fares better than Sinhala
Officers working in Tamil have a comparatively easier time with these tools, and the arithmetic explains it. Tens of millions of Tamil speakers worldwide, including in India's Tamil Nadu, have contributed an immense body of Tamil literature and digital material to the internet. Sinhala is spoken by roughly twenty million people, almost all within one country, and the volume of Sinhala content published online is very limited.
What does multimodal actually mean?
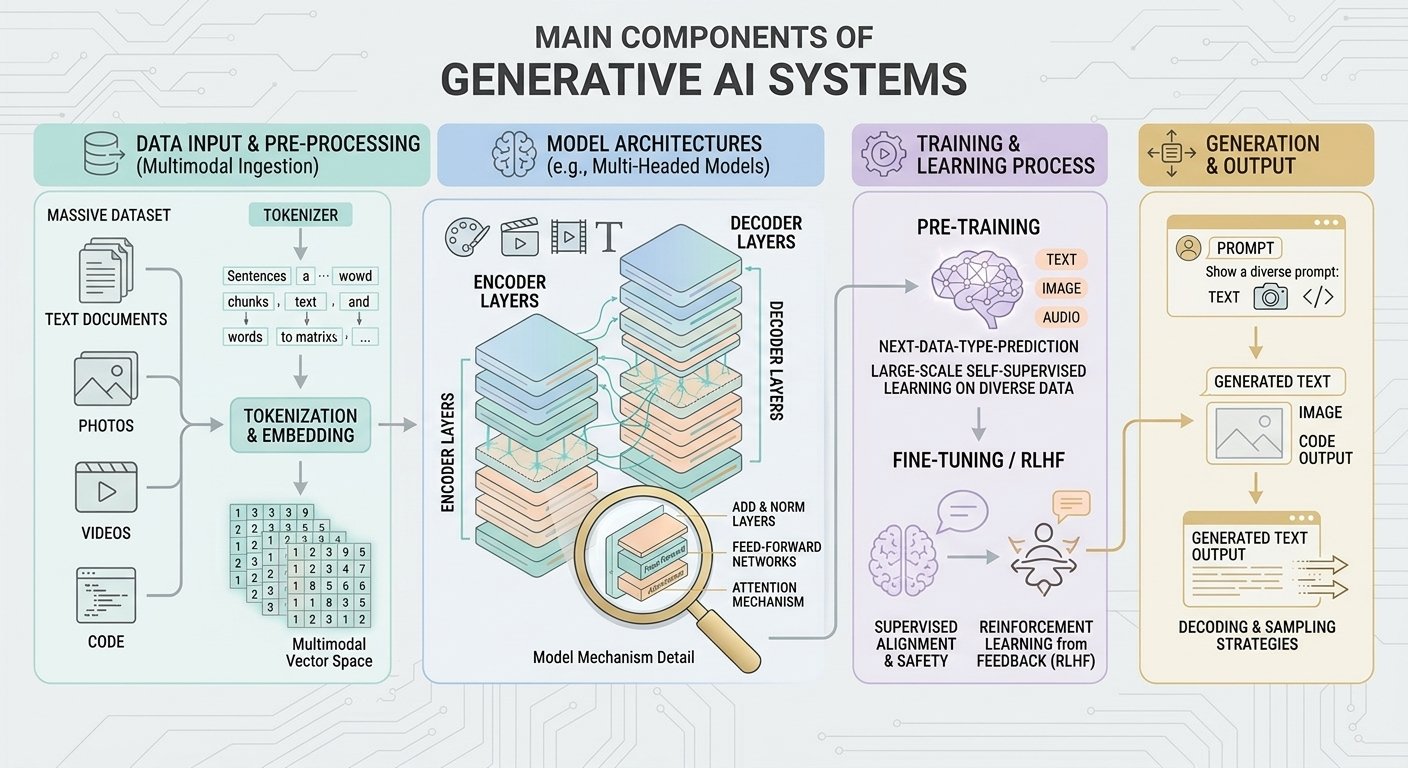 Figure 3.5: The architecture of a multimodal generative AI system — multimodal data input (text, photos, videos, audio, code), the unified multidimensional vector space, the multi-headed Transformer, and multimodal output.
Multimodal training and safety alignment
Training proceeds on mixed video, audio and text through next-data-type prediction, and the fine-tuning stage carries an additional burden here: safety guidelines and protective filters against forged media. This is not an optional extra. A system that can generate a convincing human voice from a sample is the same system that can be used to impersonate a citizen on a telephone call, and the defences against that misuse have to be trained in rather than added afterwards.
What this gives the public officer in practice
The capability becomes concrete very quickly, and these three examples are worth trying rather than reading.
Photograph an old handwritten land deed or letter and have its contents read back in a second — vision-based optical character recognition, working on handwriting that defeats ordinary scanning software. On a public day, record a citizen's spoken grievance and produce an official inquiry note immediately, while the citizen is still in front of you. Feed in the map or chart of a complex development plan and have its inconsistencies identified, where a reader would take an afternoon to find them.
Each of these replaces a specific, tedious, error-prone task that currently consumes hours of an officer's day. None of them removes the need for a human to check the result.
In the next chapter, we discuss how this natural language revolution is bringing the humanities back to center stage — and how AI closes the digital divide facing the ordinary citizen.