CM-05: Advanced Prompting Methods and Reasoning Patterns (Advanced Prompt Engineering Frameworks)
Published 2026-09-14
Core Theme: A prompt is not a question you beg a computer to answer. It is a piece of design. It builds reasoning in stages, assigns professional standpoints, and — used properly — re-engineers the way real work actually gets done, whether that work is a lesson, a household decision, or an office process.
What are the types of prompting?
Most people use generative AI the same way they use a search box. They type one line, read the first answer, decide it is good enough, and stop. For a birthday message that is perfectly fine. For a lesson plan, a marking scheme, a revision timetable, or a decision about a child's future, it is the reason the output feels shallow — and the reason so many people conclude, wrongly, that the model is not very clever.
The model is not the limiting factor. The instruction is. Over the last few years a fairly stable set of prompting methods has settled into professional practice, and they are worth learning the way a writer learns paragraph structure: not as tricks, but as standard forms you reach for depending on the job in front of you.
There are nine in common use, and they are easier to remember once you see that they answer three different questions. The first family — zero-shot, few-shot, negative and role-based prompting — shapes what the output should look like. The second family — chain-of-thought, chain-of-density and tree-of-thought — shapes how the model should think before it answers. The third family, the two retrieval methods, decides which facts the model is allowed to use at all. Figure 6.1 lays all nine out together.
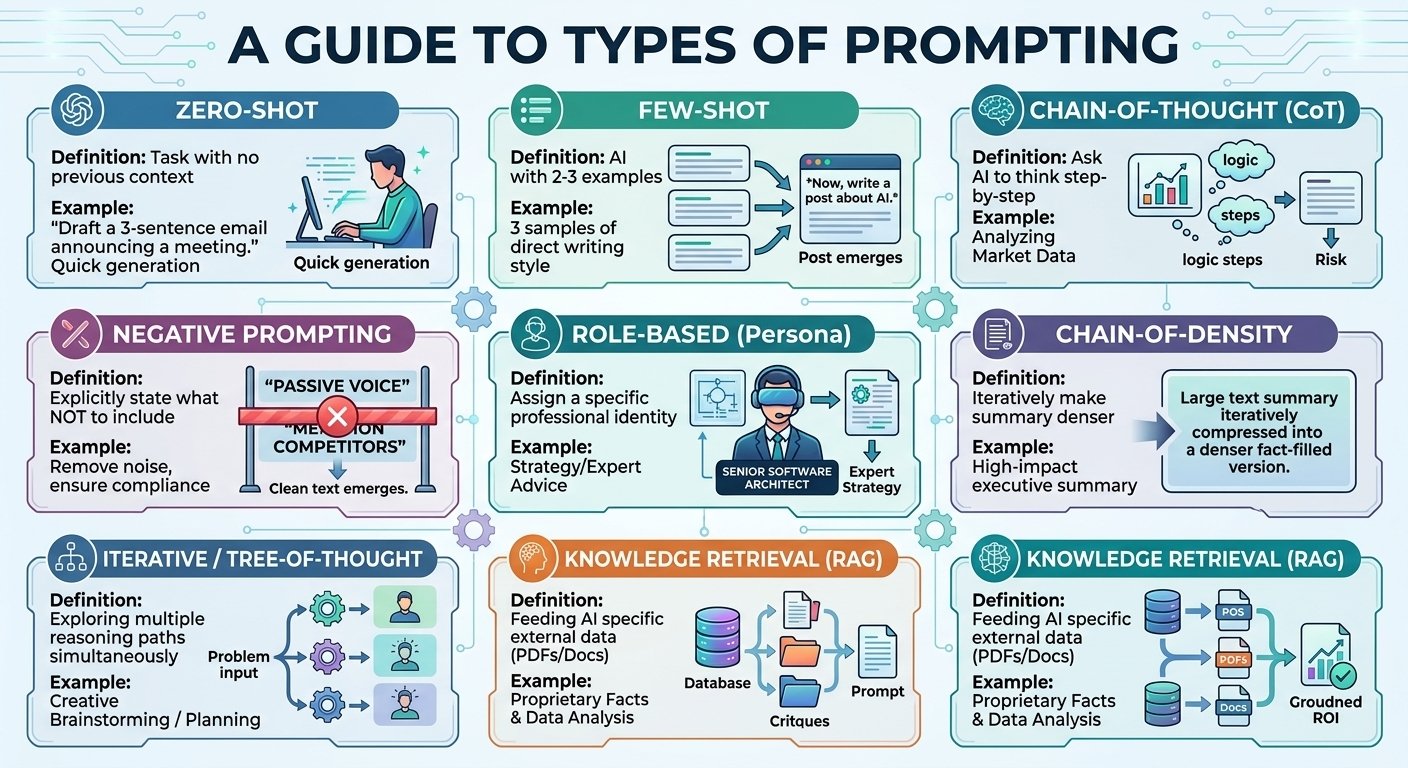 Figure 6.1: A Guide to Types of Prompting — Zero-Shot, Few-Shot, Chain-of-Thought, Negative, Role-Based, Chain-of-Density, Tree-of-Thought, and the Retrieval-Augmented (RAG) variants.
Zero-shot prompting: asking straight out
Zero-shot is the plain instruction. You describe the task, you give no examples, and you let the model draw on what it already knows. "Write a short notice to parents about tomorrow's Grade 9 parents' meeting" is a zero-shot prompt, and for that task it is the right one.
The reason zero-shot works at all is that a large model has already absorbed millions of documents of that general shape. You are not teaching it what a meeting notice is; you are only telling it which one you want today. That also tells you where zero-shot breaks down. It produces the average of everything the model has seen, which means a competent, generic result. Where your school has a house style, where an examiner expects a particular phrasing, or where a tone must not vary, the average is not good enough.
Use zero-shot for low-stakes, general work: a first draft, a summary you will read anyway, a quick explanation, a rewrite for clarity. Treat it as the default starting point, and escalate to one of the other eight methods the moment the output has to satisfy someone other than yourself.
Few-shot prompting: teaching by showing
Few-shot prompting replaces description with demonstration. Instead of explaining your style in adjectives — "formal, but warm, and concise" — you paste two or three finished examples that already have it, and then ask for a fourth in the same pattern.
This works because pattern-matching is what these models do best. Adjectives are ambiguous; a worked example is not. Two past notices that parents actually turned up for carry your school's sentence rhythm, its level of formality, its typical length and its habit of putting the date first, all at once, without you having to name any of it. The instruction becomes simple: "Following the language pattern of the notices above exactly, draft the one for the sports meet."
Few-shot is the method to reach for whenever the format matters as much as the content. A teacher building tutes in a consistent house style; a student who has two model answers that scored full marks and wants the third written to the same structure; a parent drafting a letter to the school that should match the two that got a reply. Two good examples usually outperform two paragraphs of instruction. Pick your examples with care, though: the model will faithfully copy their flaws as well as their virtues.
Chain-of-thought prompting: making the model show its working
A model asked for an answer will produce an answer. A model asked to reason will produce reasoning, and then an answer — and the second answer is usually better. That is the whole of chain-of-thought prompting: you add an instruction such as "think step by step", or better, you name the steps you want it to take.
The reason this changes the output is mechanical rather than mysterious. These systems generate text one piece at a time, each piece conditioned on everything written so far. When the intermediate steps exist on the page, later steps have something correct to build on. When they do not, the model has to leap straight to a conclusion and hope. The visible working also hands you something valuable: a trail you can audit. If the conclusion is wrong, you can see where it went wrong instead of simply distrusting the whole output.
Use chain-of-thought whenever the task has stages that depend on each other — working a multi-step mathematics problem, checking whether a student's answer lost method marks or accuracy marks, comparing three model answers to decide which earns the most credit, or planning eight weeks of revision across nine subjects. The cost is length and time. That is a fair price for work someone will rely on.
Negative prompting: naming what must not happen
Most instructions describe the desired output. Negative prompting describes the forbidden one, and it is the method most people discover last and then use every day.
The reason it matters is that a model's most dangerous habit is helpfulness. Asked for a textbook page number it does not know, it will produce a plausible-looking one, because a fluent answer scores better than an admission of ignorance. You close that gap by giving it a permitted escape route: "Never invent a textbook page number or an official definition. If you are not certain, write [teacher to verify] instead. Do not exceed 200 words." Now the model has something correct to do when it does not know, and the placeholder becomes a visible flag for a human reviewer instead of an invisible fabrication.
In learning, negative prompting carries the single most valuable instruction available to a student: "do not give me the final answer." A model told to withhold the answer and question you instead becomes a tutor; the same model without that line becomes a vending machine. The same technique removes the other irritations: nothing beyond the Grade 10 syllabus, no passive voice, no invented statistics. A short standing list of prohibitions, reused across every prompt you write, does more for output quality than almost anything else on this page.
Role-based prompting: giving the model a standpoint
Ask "is this answer any good?" and you get a bland balanced reply. Ask an experienced O/L examiner to mark the same answer against the marking scheme, and you get specific, uncomfortable, useful observations about where the method marks were lost.
Assigning a role narrows the model's field. A professional identity brings with it a vocabulary, a set of priorities, a characteristic list of worries and a standard of evidence — and by naming the role you pull all of that into the response instead of the generic middle. It costs one sentence and changes the output completely.
Role-based prompting earns its place most clearly in review and critique work, where the point is to find the weaknesses in your own thinking before someone else does. Have a lesson plan read by a strict examiner, then by a parent with no technical background, then by a student who finds the subject frightening. Each pass finds a different class of problem. It is the cheapest form of peer review available, and — as a later section shows — it becomes genuinely powerful when you stop using one role and start using a panel of them.
Chain-of-density prompting: compressing without losing the facts
Ask a model to summarise a forty-page chapter in three hundred words and it will give you three hundred words of connective tissue: "the chapter discusses several processes and introduces a number of terms." Technically a summary. Informationally close to empty.
Chain-of-density fixes this by iterating under a fixed constraint. You ask for the summary, then ask for it again in the same word count, this time folding in the specific terms, formulas and dates that the first version left out — and then again, and again. Because the length cannot grow, every round forces vague phrasing out to make room for facts. After three or four passes the same three hundred words carry everything a student actually needs.
This is the method for revision sheets, and it is the difference between notes that comfort you and notes that work. A one-page summary of a chapter that keeps every formula, every definition and every date is worth more the night before an examination than forty pages you will not reread. It applies equally to a long report you must brief someone on, or a term's worth of meeting minutes.
Tree-of-thought prompting: comparing routes before committing
Chain-of-thought follows one line of reasoning to its end. That is a weakness when the first plausible route is not the best one, because the model — like a person in a hurry — will commit to it and rationalise forward.
Tree-of-thought asks for several distinct approaches first, requires the strengths and weaknesses of each to be set out honestly, and only then asks for a recommendation with the reasoning for the choice. You are separating generation from judgment, which is exactly what a good committee does and exactly what a rushed one does not.
Reach for it when the decision has genuine trade-offs rather than a single correct answer: which A/L stream a child should take, which two of five tuition classes to keep and which to drop, how to divide eight weeks of revision between nine subjects when there is not enough time for all of them. Even when you have already made up your mind, the discarded branches are useful — they are the objections a relative will raise at the next family gathering.
Retrieval from documents: grounding the model in one authoritative text
The methods above improve how a model uses what it already knows. The last two change what it is allowed to know, and for serious work they matter more than all the rest.
Retrieval-augmented generation over unstructured text means supplying the source document yourself — the National Institute of Education textbook, the syllabus, the past-paper marking scheme, the school's circular — and instructing the model to answer only from its contents, quoting the passage it relied on and saying plainly when the document does not settle the question. The general knowledge baked into the model during training is frozen at some past date, averaged across the whole world, and drawn largely from other countries' curricula. The textbook in front of you is the one your examiner marks against.
This is the single most important habit for any student or teacher using AI. It converts the model from a source of claims into a very fast reader of your own sources — and it is what prevents the most common and most expensive failure in this whole series, which is an answer that is scientifically correct and earns no marks because it was never phrased the way our syllabus requires.
Retrieval from data: putting the model next to the spreadsheet
The second retrieval method connects the model to structured information rather than prose: a spreadsheet, a database, an exported list. The model's job changes from writing to querying — filtering, joining, comparing, summing, and then explaining the result in language a person can act on.
The important distinction is that the arithmetic should happen in the data layer, not in the model's head. Language models are unreliable calculators and excellent query writers. Used properly, the model turns your question into a query, the spreadsheet computes the answer, and the model explains what came back.
That pattern handles a large share of real work. A teacher with a term's mark sheet for forty students can ask which five topics the class as a whole is weakest on, and which three children slipped in the same topic — which is a different and far more useful question than the class average. A parent tracking a child's weekly practice scores can ask which subject is trending down. A small business owner can ask which fifteen invoices out of four thousand need a human decision. The value is not that the model is clever. It is that the person stops spending three days on the sorting and spends the time on the fifteen cases instead.
Choosing between the nine
In practice you rarely use one method alone. A serious prompt is usually a role, plus a reasoning instruction, plus a short list of prohibitions, plus a grounding document — four of the nine stacked into one instruction. The table below is a quick way to find your starting point.
| If the job is… | Start with | Because |
|---|---|---|
| A quick draft or explanation | Zero-shot | The model's general knowledge is already enough |
| Matching an exact house format | Few-shot | Examples carry format better than adjectives |
| Multi-step analysis or calculation | Chain-of-thought | Visible steps are both more accurate and auditable |
| Teaching yourself, not being told | Negative prompting | "Do not give the final answer" turns a tool into a tutor |
| Critique and review | Role-based | A standpoint produces specific objections, not bland balance |
| A long chapter into one revision page | Chain-of-density | Fixed length forces facts in and padding out |
| A decision with real trade-offs | Tree-of-thought | Options compared before commitment, not after |
| A question of syllabus or rules | Retrieval (documents) | Only the authoritative text can be cited |
| A question about marks or records | Retrieval (data) | The spreadsheet calculates; the model explains |
How does chain-of-thought work on a real problem?
The nine methods are easy to accept in the abstract and easy to underestimate. So it is worth watching one of them do something substantial. Of the nine, chain-of-thought is the one that scales from tidying a paragraph to redesigning a whole process — and the example below is deliberately chosen from a situation almost every Sri Lankan household recognises.
A Grade 10 student sits six hours of mathematics tuition a week, fills three notebooks, and scores 48 at the term test. The instinctive family response is a seventh hour. Read it as a pattern rather than a case study: the same reasoning chain applies to any situation where effort is high, results are flat, and nobody has asked where the effort is going.
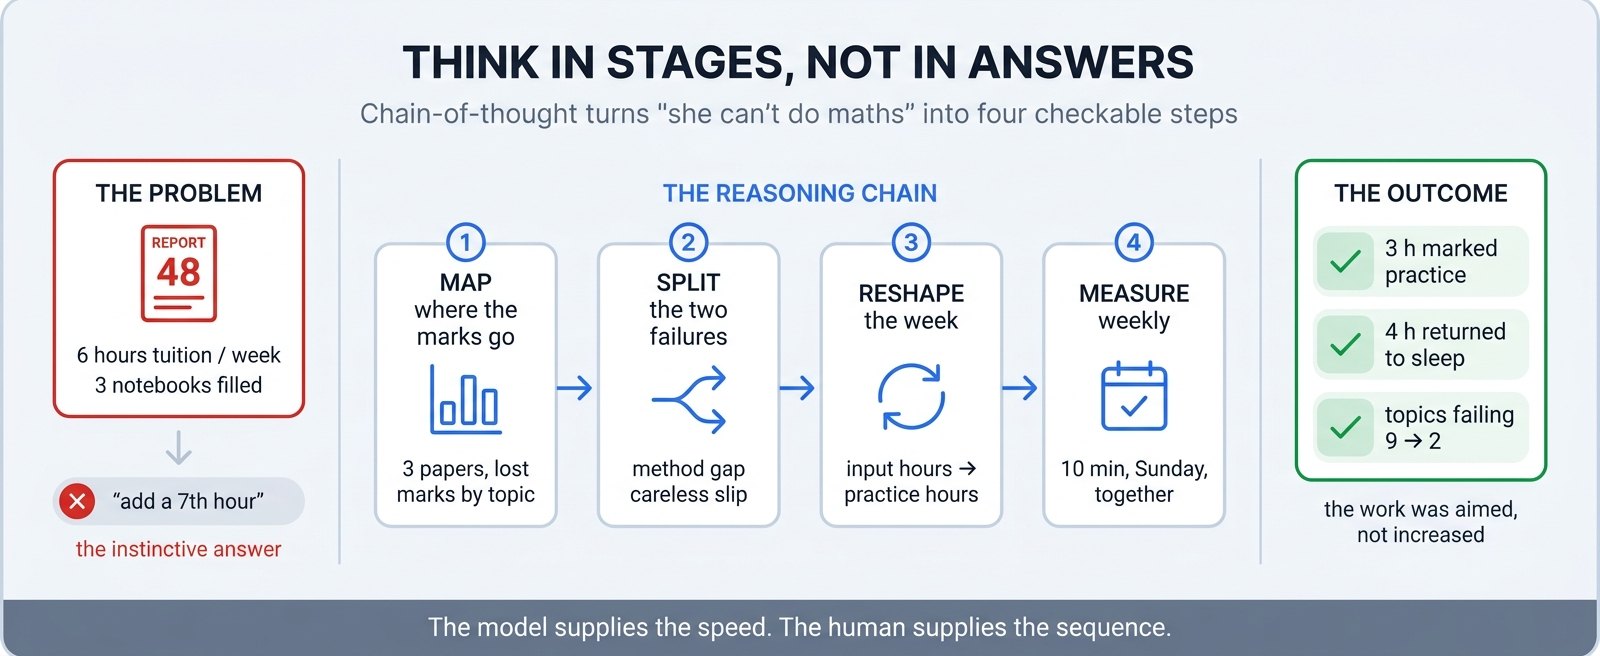 Figure 6.2: Chain-of-Thought in practice — turning "she can't do maths" into four checkable stages, and reallocating the week instead of extending it.
The instruction that started it
Notice how much work is done before the question is even asked:
"Act as an experienced O/L mathematics teacher and learning scientist. My daughter scores 48 in mathematics despite six hours of tuition a week. Do not recommend more classes until you have worked through the following, step by step: (1) map where the marks are actually being lost, (2) separate concept gaps from careless errors, (3) redesign the weekly study plan, (4) define what we measure each week and who sees it, (5) assess the expected impact."
That is three of the nine methods in a single paragraph. A role sets the standpoint. A chain-of-thought instruction forbids a leap to the answer — reinforced here by a negative constraint that blocks the model from reaching for the obvious recommendation before it has done the analysis. And rather than leaving the reasoning route to the model, the prompt names the five stages in order, which is the difference between "think step by step" as a magic phrase and chain-of-thought as engineering. The stages come from the parent's own understanding of how a diagnosis has to proceed. The model supplies the speed; the human supplies the sequence.
How the model reasoned, step by step
Step one: mapping where the marks are actually lost
The model began where any honest review begins — with evidence rather than impression. Forty-eight out of a hundred is not a single failure; it is a distribution, and nobody in the family had looked at it. Its proposed move was to take the last three term papers and tabulate the lost marks by topic, so that "bad at maths" resolves into named units. The likely finding, it noted, is that most of the loss concentrates in three or four topics while the rest of the syllabus is sound.
Step two: separating concept gaps from careless errors
Next it split those lost marks in two. A mark lost because the method was wrong and a mark lost because a minus sign was copied as a plus are the same on the report and completely different in what they require. The first needs re-teaching; the second needs attention training. Its recommendation was to mark three past papers with method and accuracy scored separately — and it predicted that a student at 48 with six hours of tuition is far more likely to be losing accuracy marks than method marks, because six hours of instruction rarely leaves a student ignorant of the method.
Step three: redesigning the week
Here the reasoning stopped diagnosing and started redesigning. The existing week is almost entirely input: sitting in halls, copying from boards, reading notes. In that structure the student never produces an answer unaided until the examination does it to them.
The proposal was to convert roughly half the tuition hours into active practice — past papers written alone, under time, then marked — and to return the travel hours to sleep. The same total hours, differently shaped. It is worth noticing that this required no new resource and no additional money; only a different arrangement of what the family was already spending.
Step four: deciding what gets measured, and who sees it
Finally, the control that makes the redesign survive contact with a busy term. Without a weekly measure, a study plan quietly decays back into whatever is easiest. The model's response was a single weekly artefact: a short list of which topics moved from red to green, reviewed by parent and child together for ten minutes on a Sunday.
Note the general principle, which carries well beyond this example — a process improvement without a measurement loop is a good intention. The measure does not need to be elaborate. It needs to exist, and somebody has to look at it.
What changed for the student
The fifth stage of the prompt asked for impact, and this is where a diagnosis becomes an argument. Six hours of tuition and four hours of travel become three hours of marked practice, three hours of tuition retained for the topics where a teacher genuinely helps, and four hours returned to sleep. The topics failing on the weekly review fall from nine to two over a term. And the mark rises not because the child worked harder, but because the work was aimed.
Hold on to the shape of that outcome, because it is the test of whether an AI-assisted redesign was worth the effort. Not "we tried a new app", but "the child stopped losing marks in the four topics where the marks were actually going". State your impact in the units the person lives in — marks, hours, rupees, nights of sleep — and the case makes itself.
Why give the model a role — and which roles?
A single expert reviewing a plan finds the problems that expert is trained to see, and misses the rest. This is why schools hold staff meetings and families argue at dinner, and it is the reason role-based prompting becomes far more powerful when you stop using one persona and start assembling a panel.
The practical method is to take a plan — the redesigned study week above, say — and run it past four different standpoints in four separate conversations, each with its own priorities and blind spots. What comes back is not four versions of the same review. It is four different sets of objections, and the gaps between them are usually where the real risk is hiding.
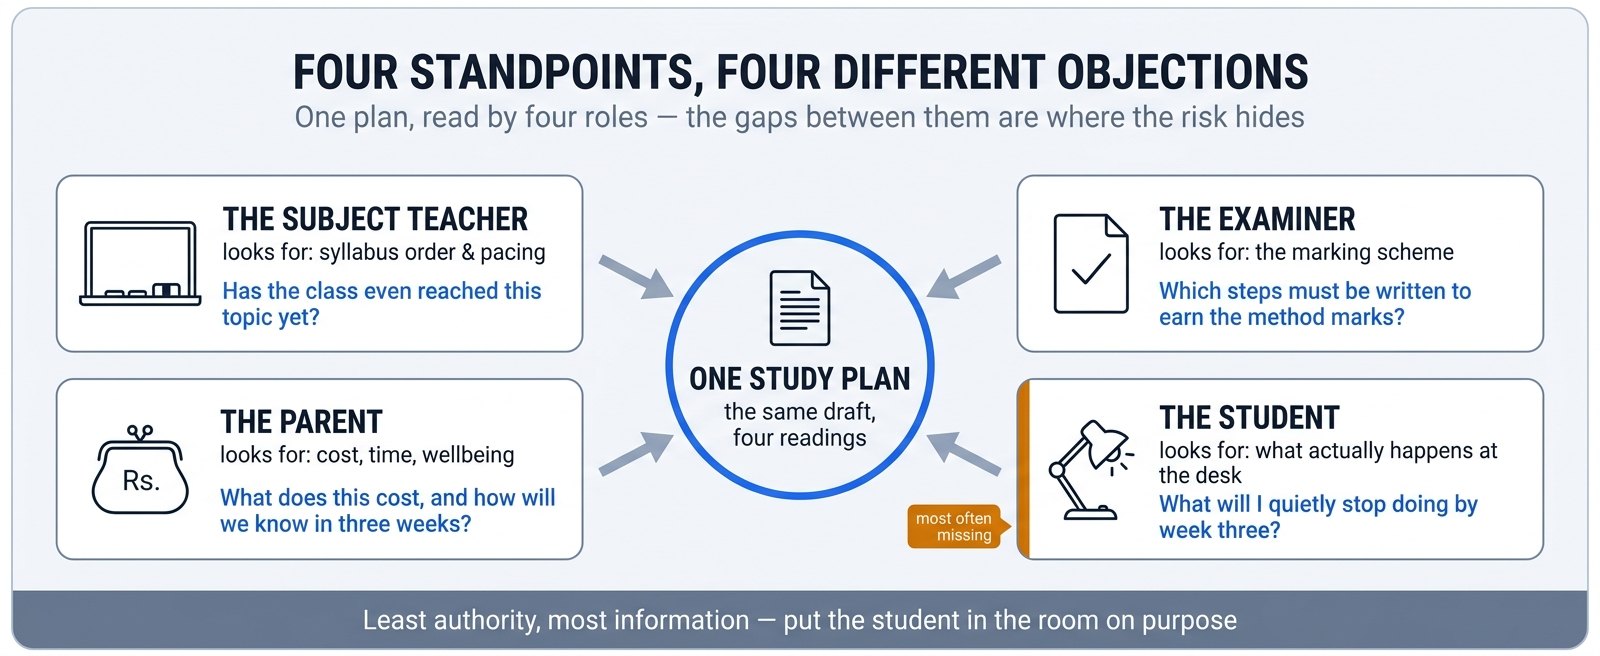 Figure 6.3: Role-Based (Persona) Prompts — the same study plan read by the subject teacher, the examiner, the parent, and the student.
Four standpoints surround almost any decision about a child's learning, and each one is routinely missing from the room.
The subject teacher: the view from the syllabus
The first standpoint is professional. A mathematics teacher with fifteen years of O/L classes knows which topics carry the most marks, which ones every cohort finds hard, and how long the syllabus actually takes to cover. Framing the model that way and asking it to identify three risks in the redesigned plan produces a category of answer a parent never volunteers — that cutting tuition in a topic the child has not yet met is different from cutting it in one already covered, and that the revision order matters because later units depend on earlier ones.
This is the standpoint that catches the most common failure of enthusiastic home reform: a plan that is well-reasoned in the abstract and out of step with the sequence the class is actually teaching.
The examiner: the view from the marking scheme
The second standpoint is the one most often skipped, and the most expensive to skip. An examiner does not care how well the child understands. They care what is written on the page, in what order, and whether it matches the scheme.
Asked from that seat, the useful questions become specific: which steps must appear in writing to earn the method marks even when the final answer is wrong, and which perfectly correct phrasings earn nothing because they are not the syllabus's wording. Every household preparing a child for a national examination is ultimately optimising for this reader — and almost nobody consults them.
The parent: the view from cost and wellbeing
The third standpoint holds the constraints the other two ignore. A parent paying Rs. 22,000 a month across all her daughter's subjects, watching her sleep five and a half hours, and unable to help with the mathematics itself, has a different set of questions: what does this plan cost, what happens to the child's health, and how will we know in three weeks whether it is working rather than in December?
Systems designed without the person paying for them and living with them tend to be unaffordable or exhausting. This standpoint exists to insist that the plan fit inside a real household.
The student: the view from the desk
The fourth standpoint speaks for the person the plan is least likely to have consulted: the child. The question it puts is blunt — what in this plan will I quietly stop doing by week three, and why?
The answers are usually practical and slightly embarrassing for the adults: the practice paper needs a quiet place that does not exist in the evening, or the schedule assumes an energy level that does not survive a 9 p.m. bus. Of the four standpoints this is the one with the least authority and the most information, and putting it into the conversation deliberately, every time, is one of the quietly serious uses of this technology.
What is a Promptathon, and how do you run one?
Everything above is an individual skill. The obvious next question for anyone responsible for an institution — a school, a department, a tuition institute, a business — is how to get a hundred colleagues doing it. And the usual answer, hiring an outside firm to build a system, has a well-documented failure pattern. The vendor does not know which lesson every cohort stumbles on, which form field parents always leave blank, or which exception eats a Thursday afternoon. That knowledge sits in the heads of the staff, and it is generally never written down.
A Promptathon is a structured workshop for getting it out of their heads. The premise is that the people who run the process already possess its logic; what they lack is a way to express it in a form a machine can execute.
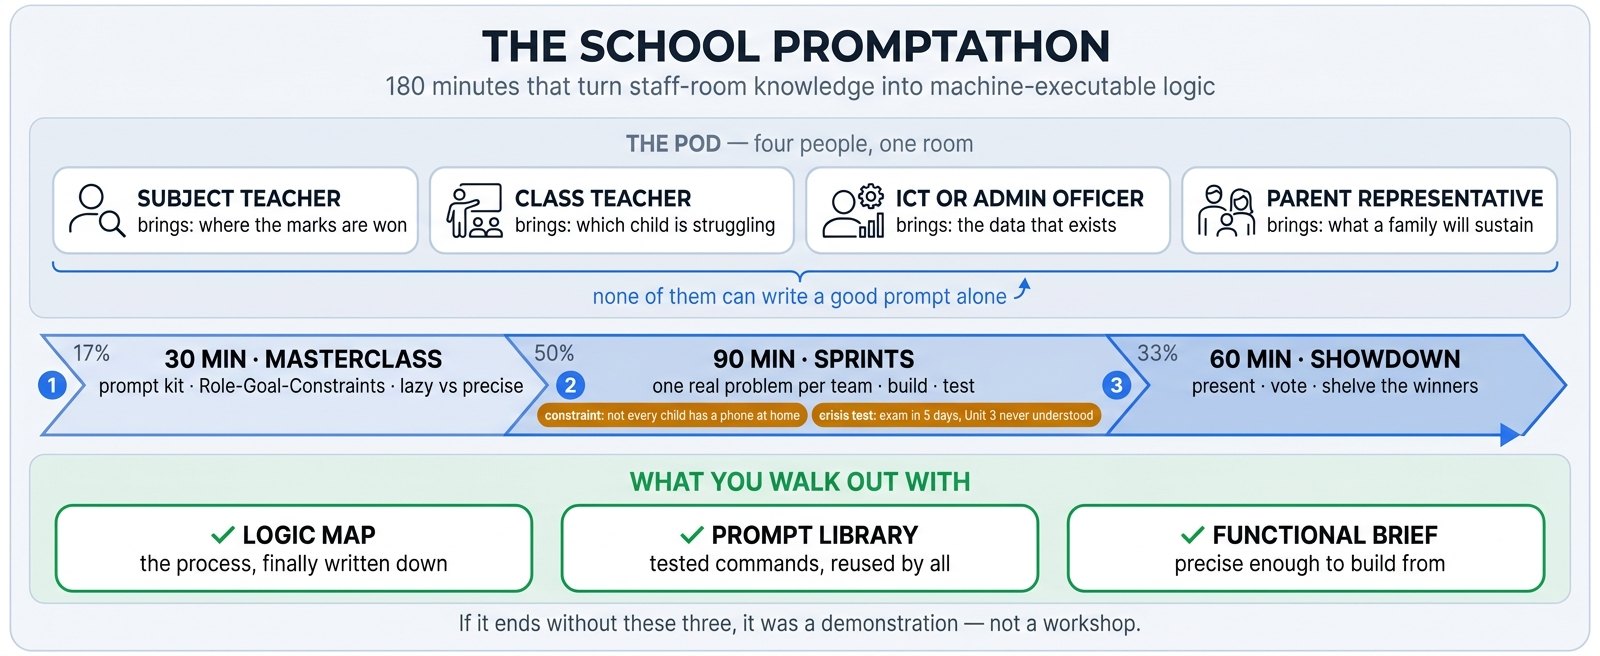 Figure 6.4: The School Promptathon — the 180-minute blueprint for turning staff-room expertise into a tested prompt library.
Who needs to be in the room
The unit that works is a small mixed pod rather than a training class, because each member holds a different piece of the same system. In a school, that pod is four people. The subject teacher brings curriculum knowledge and knows where the marks are won. The class teacher or counsellor brings the daily friction — which children are struggling, what is happening at home, how the day actually runs as opposed to how the timetable says it does. The ICT or administrative officer brings the data that exists, the systems that hold it, and the hard constraints. And a parent representative brings the reality of the home: what is affordable, what fits around work, and what a family will actually sustain.
None of the four can write a good prompt alone. Together, in one session, they can — and the argument between them is not an obstacle to the work. It is the work, because it surfaces disagreements about the process that have been quietly coexisting for years.
The 180 minutes
The session runs in three phases, and the proportions matter more than the total.
The masterclass takes thirty minutes. Participants receive a prompt kit, meet the Role-Goal-Constraints framework from CM-04, and are shown, side by side, a lazy prompt and a precise one on the same task. Half an hour is deliberately short. People learn this by doing it badly and then better, not by being lectured at.
The sprints take ninety minutes, and this is the heart of the workshop. Small teams each adopt one real problem — marking turnaround, the weekly message home, revision planning for a weak topic — and build prompts for it. Three rules keep the work honest. The ICT officer imposes real constraints as the teams go — "do not assume every child has a smartphone at home" — so nothing is designed for a school that does not exist. Teams work backwards from the outcome the child needs rather than forwards from the form they currently fill in. And every prompt is tested against a genuine crisis case: "the examination is in five days and the student has just realised they never understood Unit 3." A prompt that only handles the ordinary case will meet the extraordinary one within a week.
The showdown and library-building take sixty minutes. Teams present their best prompts and the group votes on clarity, robustness and usefulness. Competition is not decoration here; it forces teams to make their logic legible to colleagues from other subjects, which is the same test the prompt will face in daily use. Winning prompts go into the institution's shared prompt library.
A worked exercise: the message home that motivates instead of wounding
One exercise from the sprint phase shows how much collaborative judgment a single prompt can carry. The task: compose the message a parent receives when their child has fallen behind in a subject, such that the parent ends up motivated rather than angry — and the child does not pay for it that evening.
Each member of the pod contributes a constraint. The class teacher, who takes the distressed phone calls, insists on a Grade-6 reading level and on naming one specific next step rather than a general concern. The subject teacher supplies what is actually true about the gap and how recoverable it is. The ICT officer supplies the data variables the system can populate — {Student_Name}, {Subject}, {Topic} — because a template asking for data nobody holds will never be sent. And the parent representative insists the message state plainly that this is fixable and that no blame attaches to the child, since the unspoken fear behind every such message is that it is a verdict rather than a report.
Four people, one short message, fifteen minutes. The result is better than any of them would have produced alone, and it is now reusable for every child in the school.
What you take away
A Promptathon should end with three artefacts, and if it does not, it was a demonstration rather than a workshop.
The first is a logic map: a step-by-step chain-of-thought blueprint for each major process, which is the institution's own working knowledge finally written down. The second is a prompt library: a tested, verified command set for the recurring tasks, so the next colleague facing the same job starts from a working instruction rather than a blank box. The third is a functional brief — a specification precise enough for whoever builds the eventual system to work from without guessing, which is the single most common missing document in failed software projects of every kind.
Tip
Remember: A Promptathon is not playtime with AI. It is the documentation of decades of human professional expertise into precise technical logic a computer can execute. A school staff, a business team, a government department — even a family planning a move abroad — can run the same three phases on their own problem.
In the next module we turn the argument around and look at where this powerful tool goes wrong in our hands: the seven risks of generative AI, the $440,000 Deloitte lesson, and the protective walls of responsible use.